❌

Normale Ansicht

DoorDash will start paying gig workers for creating content to train AI models

DoorDash has launched a new option for its gig economy workers to earn some extra cash. The delivery service introduced Tasks, which it describes as "short activities Dashers can complete between deliveries or in their own time." It gives taking pictures of restaurant dishes or recording video of unscripted conversations in languages other than English as examples. These materials will be used to train artificial intelligence and robotics models. 

A representative from DoorDash told Bloomberg News that it will use Tasks content for evaluating its in-house AI models as well as those made by its partner companies in retail, insurance, hospitality and tech. DoorDash is piloting a standalone app for Tasks where Dashers will submit their content. The blog post notes that pay will be displayed upfront, and compensation will vary based on the complexity of the activity.

This idea isn't new. We've seen other startups in AI and robotics offering payment for content filmed by regular people. Considering how many lawsuits are underway against AI companies that have already benefited from unauthorized use of copyrighted materials, at least this approach lets people be directly compensated for training content.

This article originally appeared on Engadget at https://www.engadget.com/ai/doordash-will-start-paying-gig-workers-for-creating-content-to-train-ai-models-204048743.html?src=rss

©

  •  

Defense Department says Anthropic poses 'unacceptable risk' to national security

The Department of Defense said giving Anthropic continued access to its warfighting infrastructure would “introduce unacceptable risk” to its supply chains in a court filing submitted in response to the AI company’s lawsuit. If you’ll recall, Anthropic sued the government to challenge the supply chain risk designation it received for refusing to allow its model to be used for mass surveillance and the development of autonomous weapons.

In its filing, the department explained that its secretary, Pete Hegseth, had a provision incorporated into AI service contracts, allowing the agency to use their technologies for any lawful purpose. Anthropic refused its terms and apparently, the company’s behavior caused the Pentagon to question whether it truly was a “trusted partner” that it could work with when it comes to “highly sensitive” initiatives. “After all, AI systems are acutely vulnerable to manipulation, and Anthropic could attempt to disable its technology or preemptively alter the behavior of its model either before or during ongoing warfighting operations, if Anthropic — in its discretion — feels that its corporate “red lines” are being crossed,” the Pentagon wrote in its filing. “DoW deemed that an unacceptable risk to national security,” it added, referring to the agency as the Department of War, which is the Trump administration’s preferred name for it.

It was due to those concerns that President Trump ordered federal agencies to stop using its technology, the filing reads. The company is asking the court to issue a preliminary injunction and put a pause on a ban while it’s challenging its supply chain risk designation in court. While Anthropic’s clients could continue working with the company on non-defense-related projects, it says the label could cause it to lose billions of dollars in revenue. It’s not quite clear if Anthropic is still trying to reach a new deal with the government, as was reported before it filed its lawsuit. As The New York Times notes, Microsoft, Google and OpenAI had filed friend-of-the-court briefs in support of Anthropic since then.

This article originally appeared on Engadget at https://www.engadget.com/ai/defense-department-says-anthropic-poses-unacceptable-risk-to-national-security-094328717.html?src=rss

©

  •  

Encyclopedia Britannica sues OpenAI for copyright and trademark infringement

OpenAI has been hit with another lawsuit. This time, Encyclopedia Britannica took legal action against OpenAI, accusing the company of copyright and trademark infringements, as first reported by Reuters. More specifically, Britannica alleged that OpenAI illegally used its "copyrighted content at a massive scale" when training its AI models. Not just with training, the encyclopedia company claimed that ChatGPT's responses to user queries sometimes contain "full or partial verbatim reproductions of [Britannica's] copyright articles."

Along with claims of copyright violations, Britannica argued that OpenAI was also responsible for trademark infringement. According to the lawsuit, ChatGPT generates "made-up content or 'hallucinations' and falsely attributes them" to Encyclopedia Britannica. The lawsuit doesn't specify an amount for monetary damages, but Britannica is also seeking an injunction to prevent OpenAI from repeating these accusations.

When reached out for comment, a spokesperson for OpenAI told Engadget that, "ChatGPT helps enhance human creativity, advance scientific discovery and medical research, and enable hundreds of millions of people to improve their daily lives. Our models empower innovation, and are trained on publicly available data and grounded in fair use."

It's not the first time that Britannica has filed a lawsuit against an AI company. In September, the company, which owns Merriam-Webster, also sued Perplexity for similar reasons. On the other side, OpenAI is still embroiled in a legal battle with The New York Times, which also sued the AI giant for copyright infringement.

This article originally appeared on Engadget at https://www.engadget.com/ai/encyclopedia-britannica-sues-openai-for-copyright-and-trademark-infringement-164747991.html?src=rss

©

© Britannica

Britannica Group filed a lawsuit against OpenAI for copyright and trademark infringements.
  •  

Big tech companies agree to not ruin your electric bill with AI data centers

Today the White House announced that several major players in tech and AI have agreed to steps that will keep electricity costs from rising due to data centers. Under this Ratepayer Protection Pledge, companies are agreeing to practices that are intended to protect residents from seeing higher electricity costs as more and more businesses create power-hungry data centers. Amazon, Google, Meta, Microsoft, OpenAI, Oracle and xAI have all apparently signed on. A few of the participants — Amazon, Google and Meta — had conveniently timed press releases patting themselves on the back for their participation and touting whatever other policies they have for mitigating the negative impacts of data center construction.

The main provisions of the federal pledge have tech companies agreeing to "build, bring, or buy the new generation resources and electricity needed to satisfy their new energy demands, paying the full cost of those resources." It also claims they will pay for any needed power infrastructure upgrades and operate under separate rate structures for power that will see payments made whether or not the business uses that electricity.

The pledge doesn't appear to be any form of binding agreement and there's no discussion of enforcement or a penalty for companies that don't honor the stipulated provisions. It also doesn't address any of the other impacts data centers and AI development might be having, either on local communities, on other utilities and resources, or on access to critical computing elements like RAM.

This article originally appeared on Engadget at https://www.engadget.com/ai/big-tech-companies-agree-to-not-ruin-your-electric-bill-with-ai-data-centers-230102956.html?src=rss

©

  •  

The Supreme Court doesn't care if you want to copyright your AI-generated art

As AI-generated artwork becomes more commonplace, it still won't be able to be copyrighted, according to US courts. On Monday, the US Supreme Court declined to hear a case about whether an artwork generated with the help of AI can be copyrighted. The refusal means that a lower court's decision to reject the copyright request will stand.

The case dates back to 2018 when Stephen Thaler applied for a copyright of an artwork called A Recent Entrance to Paradise. Unlike using ChatGPT or Midjourney, Thaler, a computer scientist, created an AI system that generated the artwork in question. However, the US Copyright Office rejected his application in 2022 on the grounds that it wasn't made by a human author. Thaler sought appeals at higher courts, but ultimately had to escalate the case to the Supreme Court after both a federal judge in Washington and the US Court of Appeals ruled against him.

With a refusal from the highest court in the US, it's unlikely Thaler's case can continue. The US Supreme Court could always hear a related case in the future, but Thaler's lawyers said, "even ⁠if it later overturns the Copyright Office’s test in another case, it will be too late," adding that the decision will have negatively impacted the creative industry during "critically important years." It's worth noting that Thaler also filed applications to the US Patent and Trademark Office for AI-generated inventions, which were rejected for similar reasons.

This article originally appeared on Engadget at https://www.engadget.com/ai/the-supreme-court-doesnt-care-if-you-want-to-copyright-your-ai-generated-art-171849407.html?src=rss

©

© REUTERS / Reuters

The U.S. Supreme Court, where justices are expected to issue opinions in pending cases, in Washington, D.C., U.S., February 25, 2026. REUTERS/Kevin Lamarque TPX IMAGES OF THE DAY
  •  

Sony faces a $2.7 billion antitrust lawsuit in the UK

Another major antitrust lawsuit has launched in the UK. This time its against Sony, which could be on the hook for almost £2 billion ($2.7 billion) for overcharging PlayStation users. 

A class action case for about 12.2 million users argues that Sony "occupies a dominant position in relation to the digital distribution of PlayStation games and in-game content and that it has been unfairly charging its UK customers too much for digital games and in-game content purchased through the PlayStation Store."

It argues that Sony "has a near monopoly" on add-on content and digital games through the PlayStation store, allowing it to set the prices and take a 30 percent commission.

The class action encompasses anyone in the UK who owned a PlayStation console and purchased digital games or made in-game purchases through the PlayStation store between August 19, 2016 and February 12, 2026. It's being run as an opt-out lawsuit, so anyone meeting the criteria can qualify without taking any action. If the lawsuit is successful then each person could receive about £162 ($217). 

Sony has argued that allowing downloads from third-party stores could bring security and privacy risks, according to the Financial Times. It further states that the digital sales commission makes up profits lost for selling their consoles with minimal profit. 

This lawsuit follows the success of a similar class action decided in October. The UK's Competition Appeal Tribunal found that Apple had been abusing its dominant market position and overcharging App Store users. In December, Apple filed an appeal against the £1.5 billion ($2 billion) fine. 

This article originally appeared on Engadget at https://www.engadget.com/big-tech/sony-faces-a-27-billion-antitrust-lawsuit-in-the-uk-114113889.html?src=rss

©

© Mat Smith for Engadget

Sony has sold 84.2 million PlayStation 5s since launch
  •  

Google and OpenAI employees sign open letter in ‘solidarity’ with Anthropic

Hundreds of employees at Google and OpenAI have signed an open letter urging their companies to stand with Anthropic in its standoff with the Pentagon over military applications for AI tools like Claude.

The letter, titled “We Will Not Be Divided,” calls on the leadership of both companies to “put aside their differences and stand together to continue to refuse the Department of War’s current demands for permission to use our models for domestic mass surveillance and autonomously killing people without human oversight.” These are two lines that Anthropic CEO Dario Amodei has said should not be crossed by his or any other AI company.

As of publication, the letter has over 450 signatures, almost 400 of which come from Google employees and the rest from OpenAI. Currently, roughly 50 percent of all participants have chosen to attach their names to the cause, with the rest remaining anonymous. All are verified as current employees of these companies. The original organizers of the letter aren’t Google or OpenAI employees; they say are unaffiliated with any AI company, political party or advocacy group.

The open letter is the latest development in the saga between Anthropic and US Defense Secretary Pete Hegseth, who threatened to label the company a “supply chain risk” if it did not agree to withdraw certain guardrails for classified work. The Pentagon has also been in talks with Google and OpenAI about using their models for classified work, with xAI coming on board earlier this week. The letter argues the government is "trying to divide each company with fear that the other will give in.”

OpenAI CEO Sam Altman told his employees on Friday that the ChatGPT maker will draw the same red lines as Anthropic, according to an internal memo seen by Axios. He told CNBC on the same day that he doesn't "personally think the Pentagon should be threatening DPA against these companies."

This article originally appeared on Engadget at https://www.engadget.com/ai/google-and-openai-employees-sign-open-letter-in-solidarity-with-anthropic-194957274.html?src=rss

©

© Kayla Bartkowski via Getty Images

ARLINGTON, VIRGINIA - APRIL 16: U.S. Secretary of Defense Pete Hegseth speaks during a meeting with El Salvador Minister of National Defense René Merino Monroy at the Pentagon on April 16, 2025 in Arlington, Virginia. The meeting comes following the illegal deportation by the Trump administration of Kilmar Armando Abrego Garcia, a Maryland man who has been held in prison in El Salvador since March 15. (Photo by Kayla Bartkowski/Getty Images)
  •  

Meta sues advertisers in Brazil and China over 'celeb bait' scams

Meta has sued the people and groups behind three scam operations that used images and deepfakes of celebrities to lure users to scam websites. According to the company, the three entities were based in China and Brazil and targeted people in the US, Japan and other countries. The ads promoted fraudulent investment schemes and fake health products.

Meta said that it had filed lawsuits against several people in Brazil who promoted fake or unapproved healthcare products and online courses promoting them. The company also sued a China-based entity it says used ads featuring celebrities "as part of a larger fraud scheme that lured people into joining so-called investment groups." The company didn't provide details on how many ads these groups had run on Facebook, how many social media users had seen or interacted with the ads or how long the scammers had been operating on the platform.

So-called "celeb bait" ads have been a long-running issue for the company. Engadget has previously documented celeb bait scams on Facebook, including ones that frequently use Elon Musk and Fox News personalities to hawk fake cures for diabetes. The Oversight Board has also criticized the company for not doing enough to combat such scams. In its update, Meta says that "because scam ads are designed to look real, they’re not always easy to detect." The company also noted that it has now enrolled "more than 500,000" celebrities and public figures into its facial recognition system that's meant to automatically detect scam ads using the faces of famous people. 

Meta's handling of scammy advertisers has come under increased scrutiny in recent months after Reuters reported that researchers at the company at one point estimated that as much as 10 percent of its ad revenue could be coming from scams and banned products. The fact that Meta has made billions of dollars from problematic advertisers has also caused the company to be slow to take action against repeat offenders.

In addition to the groups behind the celeb bait ads, Meta says that it's upgraded its ability to detect scam ads that use cloaking, which has at times hindered its internal review systems. The company also sued a Vietnam-based advertiser it says used scam ads to hawk "deeply discounted items from well-known brands," including Longchamp.

Meta also took legal action against eight former "Meta Business Partners," who promoted services that would "un-ban" or other "account restoration services." The company says it will "consider taking additional legal action, including litigation, if they don’t comply" with cease and desist orders.

Update, February 26, 2026, 1:16PM PT: This story was updated to specify that Meta’s internal estimates around ad revenue included scams and banned products.

This article originally appeared on Engadget at https://www.engadget.com/social-media/meta-sues-advertisers-in-brazil-and-china-over-celeb-bait-scams-190000268.html?src=rss

©

  •  

NY AG: Valve's loot boxes can get kids hooked on gambling

New York Attorney General Letitia James has accused Valve of promoting illegal gambling through its video games in a lawsuit filed by her office. According to the AG’s announcement, her office conducted an investigation and had concluded that Valve enabled gambling by enticing users to pay for a chance at rare items from loot boxes in Counter-Strike 2, Team Fortress 2 and Dota 2. In the lawsuit, the New York AG stressed that Valve’s loot boxes are “particularly pernicious,” because the games are popular among children and teenagers.

The lawsuit described the loot box model, which requires a player to open a mystery chest for the possibility of winning rare items, as “quintessential gambling.” It argued that people introduced to gambling at an early age are at a significantly higher risk of developing gambling addictions later on, based on research. In addition, it explained that gambling is mostly illegal in New York.

Players have to pay for chests or boxes and the keys to be able to open them in Valve’s games, and the company has reportedly sold billions of dollars’ worth of keys for Counter-Strike alone. The lawsuit said that Valve has made tens of millions of dollars in fees from the sale of virtual items on the Steam Community Market, as well. In addition to being able to sell items on Steam for funds directly credited to their Steam Wallet, players can also sell on third-party marketplaces for cash.

According to James’ office, Valve facilitates and even assists third-party marketplaces in their operations, based on its investigation. Engadget has asked Valve for a statement about the lawsuit, but we have yet to hear back. However, the company previously denied being involved with third-party marketplaces that allow the sales of its game items for real-world money. In a response to an inquiry by the Danish Gambling Authority, Valve explained that those third-party websites create sock puppet accounts to sell and receive items on Steam in exchange for cash. “[T]his behavior is in violation of our terms of service,” Valve said.

The lawsuit also pointed out that there’s a huge market for Counter-Strike skins and referenced a Bloomberg article from 2025, which reported that the market for those skins had already surpassed $4.3 billion. As an example of in-game items sold for real money, it cited the sale of a Counter-Strike 2 AK-47 skin in 2024 for $1 million. The Attorney General’s Office wants the court to stop Valve from violating New York laws, to give up money it allegedly earned from illegal activities and to pay a fine three times what it allegedly earned from illegal business practices.

The most expensive skin in Counterstrike history was publicly sold this morning, a StatTrak Factory New AK-47 Blue Gem pattern 661

For over $1 million pic.twitter.com/1FdxoNM2ov

— Jake Lucky 🔜 GDC (@JakeSucky) June 5, 2024

This article originally appeared on Engadget at https://www.engadget.com/gaming/ny-ag-valves-loot-boxes-can-get-kids-hooked-on-gambling-122503556.html?src=rss

©

  •  

xAI's trade secret lawsuit against OpenAI has been dismissed

OpenAI has successfully convinced the court to dismiss the lawsuit filed by Elon Musk’s xAI, accusing the company of stealing its trade secrets. In her decision, US District Judge Rita F. Lin wrote that xAI’s complaint “does not point to any misconduct by OpenAI” and instead attributes all listed misconducts to its eight former employees who “ left for OpenAI at around the same time.”

Lin said that xAI accused two of its former employees of stealing its source code before leaving at a time when they were already speaking to an OpenAI recruiter. However, the company didn’t say if the recruiter told those former employees to do so. xAI’s lawsuit also accuses two other former employees of keeping their work chats on their devices even after leaving, another of refusing to provide certifications related to confidential information after his departure, and another of unsuccessfully trying to access xAI hiring and datacenter optimization information when he was already working for OpenAI.

“Notably absent are allegations about the conduct of OpenAI itself,” the judge noted. xAI didn’t include any information that directly accuses OpenAI of making those employees steal its trade secrets. It also didn’t include allegations that those former employees used any stolen trade secrets after they were already working for OpenAI. To be precise, OpenAI’s motion for dismissal was granted with leave to amend, so the lawsuit may not be completely over just yet. That means xAI can still file an amended complaint addressing what the judge wrote in her decision until March 17, 2026.

OpenAI and xAI have a longstanding feud, and this is just one of the several lawsuits between the two companies. In fact, Musk has an ongoing complaint against OpenAI and Microsoft, accusing the former of violating its nonprofit status. Musk, who was an early funder of OpenAI, is now asking the company for $79 billion to $134 billion in damages from “wrongful gains.”

This article originally appeared on Engadget at https://www.engadget.com/ai/xais-trade-secret-lawsuit-against-openai-has-been-dismissed-101912599.html?src=rss

©

  •  

Mark Zuckerberg testifies in social media addiction trial that Meta just wants Instagram to be 'useful'

Mark Zuckerberg took the stand Wednesday in a high-profile jury trial over social media addiction. In an appearance that was described by NBC News as "combative," the Facebook founder reportedly said that Meta's goal was to make Instagram "useful" not increase the time users are spending in the app. 

On the stand, Zuckerberg was questioned about a company document that said improving engagement was among "company goals," according to CNBC. But Zuckerberg claimed that the company had "made the conscious decision to move away from those goals, focusing instead on utility," according to The Associated Press. "If something is valuable, people will use it more because it’s useful to them,” he said. 

The trial stems from a lawsuit brought by a California woman identified as "KGM" in court documents. The now 20-year-old alleges that she was harmed as a child by addictive features in Instagram, YouTube, Snapchat and TikTok. TikTok and Snap opted to settle before the case went to trial. 

Zuckerberg was also asked about previous public statements, including his remarks on Joe Rogan's podcast last year that he can't be fired by Meta's board because he controls a majority of the voting power. According to The New York Times, Zuckerberg accused the plaintiffs' lawyer of "mischaracterizing" his past comments more than a dozen times.  

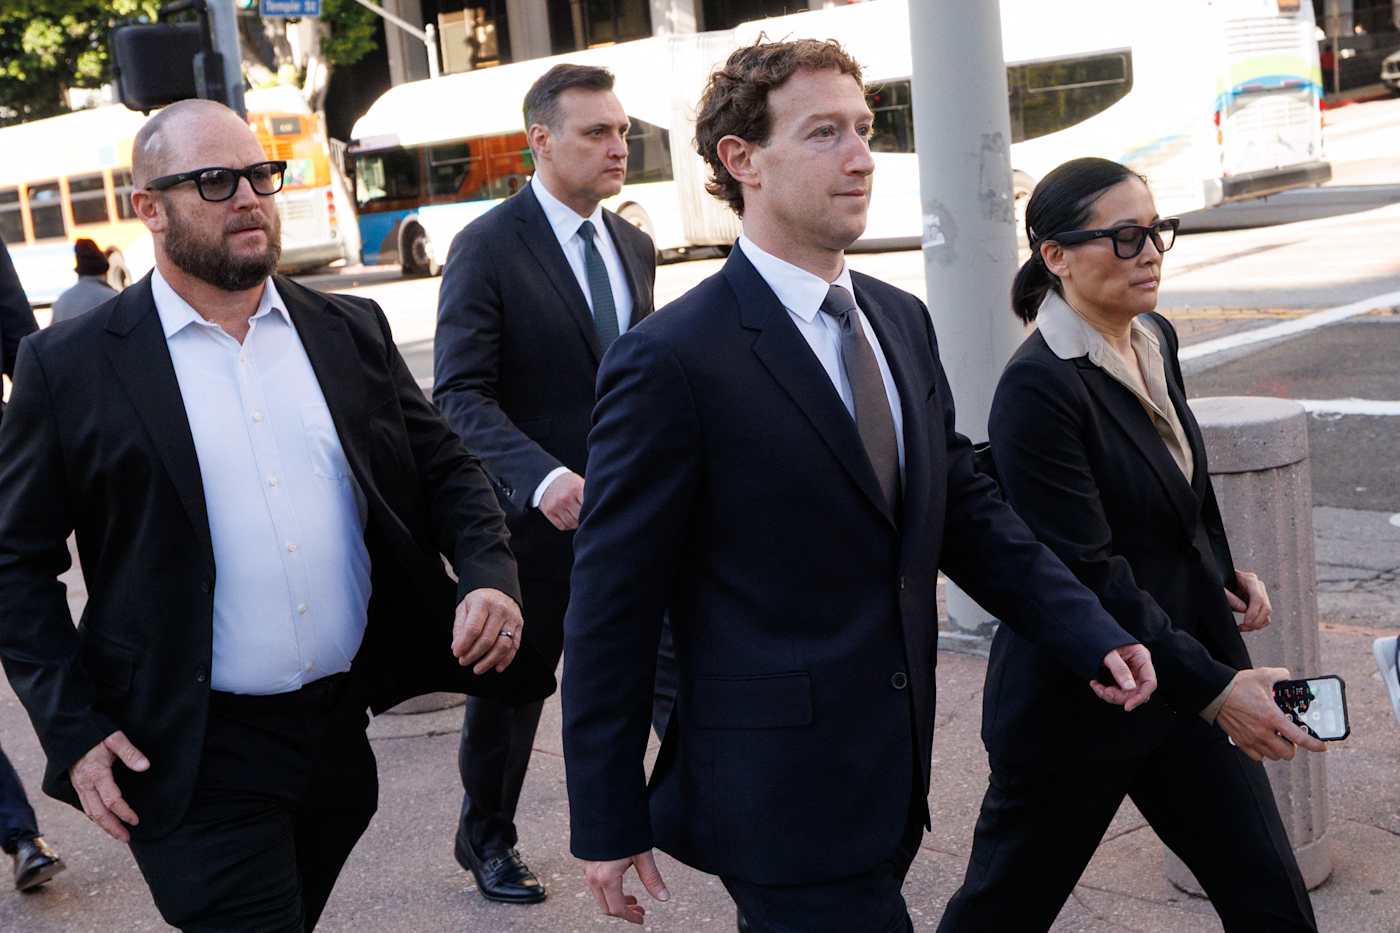
Zuckerberg's appearance in court also apparently prompted the judge to warn people in the courtroom not to record the proceedings using AI glasses. As CNBC notes, members of Zuckerberg's entourage were spotted wearing Meta's smart glasses as the CEO was escorted into the courthouse. It's unclear if anyone was actually using the glasses in court, but legal affairs journalist Meghann Cuniff reported that the judge was particularly concerned about the possibility of jurors being recorded or subjected to facial recognition. (Meta's smart glasses do not currently have native facial recognition abilities, but recent reports suggest the company is considering adding such features.)

The Los Angeles trial has been closely watched not just because it marked a rare in-court appearance for Zuckerberg. It's among the first of several cases where Meta will face allegations that its platforms have harmed children. In this case and in a separate proceeding in New Mexico, Meta's lawyers have cast doubt on the idea that social media should be considered a real addiction. Instagram chief Adam Mosseri previously testified in the same Los Angeles trial that Instagram isn't "clinically addictive."

This article originally appeared on Engadget at https://www.engadget.com/social-media/mark-zuckerberg-testifies-in-social-media-addiction-trial-that-meta-just-wants-instagram-to-be-useful-234332316.html?src=rss

©

  •  

Tesla stops using 'Autopilot' to promote its EVs in California

Tesla has stopped using the term “Autopilot” to sell its cars in California, thereby avoiding a 30-day sales and manufacturing ban in the state. If you’ll recall, a California administrative law judge ruled in December that the automaker misled consumers by using the terms “Autopilot” and “Full Self-Driving.” The judge recommended the suspension, but the California DMV gave Tesla 60 days to remove any untrue and misleading language in its marketing materials. In its announcement, the DMV said Tesla has taken corrective action and has stopped using Autopilot for marketing. Prior to that, the automaker has already clarified that driver supervision is still needed with Full Self-Driving.

The judge was ruling on a complaint the DMV made back in 2022, wherein the agency accused Tesla of making and disseminating misleading statements. It argued that starting in May 2021, Tesla used deceptive marketing materials with the labels “Autopilot” and “Full Self-Driving Capability,” as well as claimed that the “system is designed to be able to conduct short and long-distance trips with no action required by the person in the driver’s seat.” In reality, the vehicles equipped with those features “could not at the time of those advertisements, and cannot now, operate as autonomous vehicles,” the DMV said.

A ban in California could have had a huge effect on the company, seeing as the state accounts for nearly a third of its sales in the country. Tesla also recently announced that it will stop the production of its Model S and X cars to turn its Fremont, California factory where they were being manufactured into a space for the production of its Optimus humanoid robots. Tesla has huge plans for Optimus and intends to start selling the robot to the public by the end of 2027.

This article originally appeared on Engadget at https://www.engadget.com/transportation/evs/tesla-stops-using-autopilot-to-promote-its-evs-in-california-112533060.html?src=rss

©

  •  

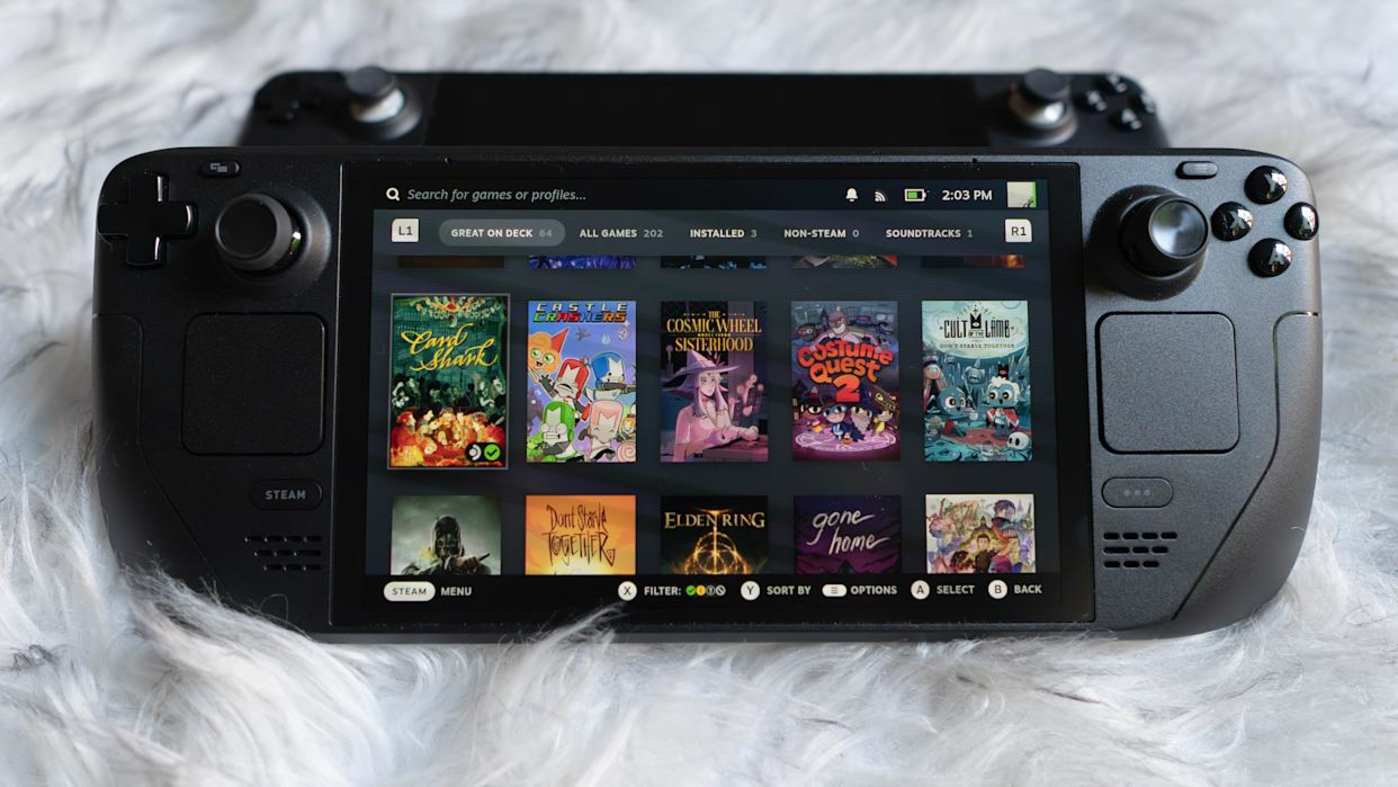
Valve admits Steam Deck availability is affected by memory and storage shortages

Don’t expect the Steam Deck to be easier to get anytime soon. Valve has posted a notice on the Steam Deck page with a warning that the handheld gaming console “may be out of stock intermittently” in certain regions “due to memory and storage shortages.” The company also reiterated that the more affordable Steam Deck LCD is no longer in production and will no longer be available once stocks run out. Valve started phasing out the LCD console back in December, which means the OLED handhelds are now the only choice for gamers who want to get a Steam Deck. The company’s notice comes after it completely ran out of Steam Deck units a few days ago.

RAM and storage shortages are plaguing tech manufacturers due to massive demand for those components from the artificial intelligence industry. AI companies have been snapping up available memory chips and hard drives for their rapid infrastructure buildouts, leaving everyone else short. In fact, we couldn’t find any deals for RAM last Black Friday, and Samsung global marketing leader Wonjin Lee warned at CES 2026 that memory price hikes are on the horizon.

Valve also had to delay the release of the Steam Machine and the Steam Frame VR headset due to industry-wide memory and storage shortages. It had intended to start shipping those devices in early 2026, but it admitted in its announcement that it has to rethink their launch date and pricing, insinuating that they could be priced higher than the company had planned,

This article originally appeared on Engadget at https://www.engadget.com/gaming/valve-admits-steam-deck-availability-is-affected-by-memory-and-storage-shortages-102913993.html?src=rss

©
  •  

DoorDashers are getting paid to close Waymo's self-driving car doors

A few days ago, a Redditor posted in the community for DoorDash drivers that they received an offer to close a Waymo vehicle’s door. The job paid a guaranteed fee of $6.25 with a $5 extra on top of it after the DoorDasher verifies that it has been completed. Waymo has confirmed to 404Media and TechCrunch that, yes, it is indeed paying Dashers to shut the doors of its self-driving cars. And it makes sense because, well, there’s nobody to do it otherwise if a passenger accidentally leaves it open.

The Alphabet subsidiary and DoorDash told the publications that it’s currently running a pilot program in Atlanta, wherein if one of its vehicle’s doors is left ajar, nearby Dashers are notified. Waymo’s self-driving vehicles can’t leave if one of its doors remains open, so the company is framing the program as a way to enhance its fleet’s efficiency. Waymo told 404Media that the program started earlier this year and that payments are structured to ensure “competitive and fair compensation for Dashers.”

To note, this isn’t the first time the two companies have teamed up. In October 2025, Waymo’s self-driving cars became a delivery option for DoorDash customers in Phoenix, Arizona. To get a Waymo delivery, customers will have to choose “opt in to autonomous delivery” during checkout and to physically retrieve their order from the car’s trunk when it arrives.

This article originally appeared on Engadget at https://www.engadget.com/transportation/doordashers-are-getting-paid-to-close-waymos-self-driving-car-doors-122711640.html?src=rss

©

  •  

EU reportedly opens another probe into Google's ads pricing

The European Commission has opened a new probe into Google, this time focused on the company's massive online advertising business, Bloomberg reports. European Union regulators have already fined Google billions for violating the Digital Markets Act, and being found guilty of anticompetitive behavior in online advertising could add to that total.

While the Commission has yet to announce a formal investigation, Bloomberg writes that it has started contacting Google's customers and competitors for information about its dominance across multiple online advertising markets. Regulators are particularly concerned that Google could be "artificially increasing the clearing price" of ad auctions "to the detriment of advertisers." If the company is found to be violating the EU's competition rules, Google could be fined 10 percent of its global annual sales.

Google's approach to advertising to minors was reportedly already under investigation by the EU as of December 2024, and besides fines, regulators have ordered the company to open up Android to competing AI assistants and share search data with rivals. In the US, there's also precedent for finding Google's approach to online advertising anticompetitive.

A US federal judge found that Google is a monopolist in online advertising in April 2025, the conclusion of a legal battle that started with a Department of Justice lawsuit accusing the company of dominating the ad market and using its control to charge more and keep a larger portion of ad sales. The DOJ ultimately wants Google to sell its ad tech business, but a final decision hasn't been reached as to how the company's anticompetitive behavior should be remedied.

This article originally appeared on Engadget at https://www.engadget.com/big-tech/eu-reportedly-opens-another-probe-into-googles-ads-pricing-194435095.html?src=rss

©

  •  

TikTok US launches a local feed that leverages a user's exact location

TikTok US just launched a local feed for users to "get the inside scoop on must-try restaurants, shops, museums and events." This is done by leveraging the exact location of people that are using the app and comes after a change in the platform's terms of service that says the app can do just that. The platform's terms of service used to note that it could collect approximate locations, but the sale to US investors looks to have changed that to precise locations.

This is an opt-in feature, despite the app potentially collecting this data whether the feed is activated or not. The feed is set to "off" by default, but can be changed via a trip to settings.

The local feed doesn't show your neighbors or people you might vibe with to help solve that pesky loneliness epidemic. Instead, it prioritizes local businesses and will highlight nearby events, shopping suggestions and restaurants to try.

The feed.
TikTok

This looks to be part of a broader push to attract small businesses to the app, both as content producers and as advertisers. As TechCrunch notes, this could also help insulate the company from future regulation and increased scrutiny, as it could point to the many small businesses that rely on its services. 

TikTok states that over 7.5 million businesses use the platform in the US to reach customers. However, this data is sourced from an Oxford Economics report from before a group of investors finalized a deal for the US version of the app.

Supporting local businesses is a noble goal, but users will have to consider whether or not the value of a dedicated feed is worth the privacy risk. Oracle is a prominent investor in the new American TikTok, and company founder Larry Ellison once said "citizens will be on their best behavior" when they are being constantly surveilled.

This local feed isn't exactly a new idea. TikTok has been trying something similar in Europe since the tail-end of last year. It has shown up in the UK, France, Italy and Germany.

This article originally appeared on Engadget at https://www.engadget.com/big-tech/tiktok-us-launches-a-local-feed-that-leverages-a-users-exact-location-170651916.html?src=rss

©

© NurPhoto via Getty Images

The TikTok logo displays on the screen of a smartphone placed on a reflective surface onto which the US flag is projected. The social network TikTok experiences technical failures and massive malfunctions following the acquisition and transfer of the Chinese app by an American consortium, in Creteil, France, on January 27, 2026. (Photo by Samuel Boivin/NurPhoto via Getty Images)
  •  

Lyft rolls out teen accounts with enhanced safety protections

Lyft has officially introduced teen accounts for ages 13 to 17. This is a rideshare feature in which teenagers can request their own rides, which is similar to Uber's pre-existing platform.

Teens request the rides on their own, but parents can keep an eye on things every step of the way. Lyft says that parents or guardians can see every ride in real time and manage the account. They also get updates at pickup and drop-off and the app allows communication with the driver when needed.

This is a rideshare service for teens, so there are several new safety features. The drivers must "meet the highest standards" on the platform. Lyft says they get annual background checks and must have "proven safe driving records, positive passenger interactions and experience behind the wheel."

The teens have to enter a PIN to ensure the correct rider gets in the car, which is something Lyft has been experimenting with for adults. Audio recording of the ride is on by default, for an added layer of safety.

Lyft Teen is available right now, though not everywhere. The company has launched the platform in 200 markets, including New York City, Chicago, Atlanta and Miami, among others. It's coming to more cities as the year winds on.

This article originally appeared on Engadget at https://www.engadget.com/apps/lyft-rolls-out-teen-accounts-with-enhanced-safety-protections-110002761.html?src=rss

©

© Unsplash / Thought Catalog

A person holding the Lyft app on a phone.
  •  

Apple just made Xcode better for vibe coding

Apple has just released Xcode 26.3, and it's a big step forward in terms of the company's support of coding agents. The new release expands on the AI features the company introduced with Xcode 26 at WWDC 2025 to give systems like Claude and ChatGPT more robust access to its in-house IDE. 

With the update, Apple says Claude and OpenAI's Codex "can search documentation, explore file structures, update project settings, and verify their work visually by capturing Xcode Previews and iterating through builds and fixes." This is in contrast to earlier releases of Xcode 26 where those same agents were limited in what they could see of a developer's Xcode environment, restricting their utility. According to Apple, the change will give users tools they can use to streamline their processes and work more efficiently than before.

Developers can add Claude and Codex to their Xcode terminal from the Intelligence section of the app's setting menu. Once a provider is selected, the interface allows users to also pick their preferred model. So if you like the outputs of say GPT 5.1 over GPT 5.2, you can use the older system. 

The tighter integration with Claude and Codex was made possible by Model Context Protocol (MCP) servers Apple has deployed. MCP is a technology Anthropic debuted in fall 2024 to make it easier for large language models like Claude to share data with third-party tools and systems. Since its introduction, MCP has become an industry standard — with OpenAI, for instance, adopting the protocol last year to facilitate its own set of connections. 

Apple says it worked directly with Anthropic and OpenAI to optimize token usage through Xcode, but the company’s adoption of MCP means developers will be able to add any coding agent that supports the protocol to their terminal in the future. Xcode 26.3 is available to download for all members of the Apple Developer Program starting today, with the Mac Store availability “coming soon.”

This article originally appeared on Engadget at https://www.engadget.com/ai/apple-just-made-xcode-better-for-vibe-coding-195653049.html?src=rss

©

  •  

Publishers are blocking the Internet Archive for fear AI scrapers can use it as a workaround

The Internet Archive has often been a valuable resource for journalists, from it's finding records of deleted tweets or providing academic texts for background research. However, the advent of AI has created a new tension between the parties. A few major publications have begun blocking the nonprofit digital library's access to their content based on concerns that AI companies' bots are using the Internet Archive's collections to indirectly scrape their articles.

"A lot of these AI businesses are looking for readily available, structured databases of content," Robert Hahn, head of business affairs and licensing for The Guardian, told Nieman Lab. "The Internet Archive’s API would have been an obvious place to plug their own machines into and suck out the IP."

The New York Times took a similar step. "We are blocking the Internet Archive's bot from accessing the Times because the Wayback Machine provides unfettered access to Times content — including by AI companies — without authorization," a representative from the newspaper confirmed to Nieman Lab. Subscription-focused publication the Financial Times and social forum Reddit have also made moves to selectively block how the Internet Archive catalogs their material.

Many publishers have attempted to sue AI businesses for how they access content used to train large language models. To name a few just from the realm of journalism:

Other media outlets have sought financial deals before offering up their libraries as training material, although those arrangements seem to provide compensation to the publishing companies rather than the writers. And that's not even delving into the copyright and piracy issues also being fought against AI tools by other creative fields, from fiction writers to visual artists to musicians. The whole Nieman Lab story is well worth a read for anyone who has been following any of these creative industries’ responses to artificial intelligence.

This article originally appeared on Engadget at https://www.engadget.com/ai/publishers-are-blocking-the-internet-archive-for-fear-ai-scrapers-can-use-it-as-a-workaround-204001754.html?src=rss

©

  •  

Music publishers sue Anthropic for $3 billion over ‘flagrant piracy’

A group of music publishers led by Concord Music Group and Universal Music Group are suing Anthropic, according to a report by Reuters. The suit accuses the AI company of illegally downloading more than 20,000 copyrighted songs, including sheet music, lyrics and compositions.

These songs were then allegedly fed into the chatbot Claude for training purposes. There are some iconic tunes named by Universal in the suit, including tracks by The Rolling Stones, Neil Diamond and Elton John, among many others. Concord is an independent publisher that handles artists like Common, Killer Mike and Korn.

The publishers issued a statement saying that the damages could amount to more than $3 billion. This would make it one of the largest non-class action copyright cases in US history.

"While Anthropic misleadingly claims to be an AI 'safety and research' company, its record of illegal torrenting of copyrighted works makes clear that its multibillion-dollar business empire has in fact been built on piracy," the lawsuit says.

The suit was filed by the same legal team as last year's Bartz v. Anthropic case. The music publishers say they found that Anthropic had been illegally downloading thousands of songs during the discovery process of that suit.

For the unfamiliar, the Bartz v. Anthropic case ended with an award of $1.5 billion to impacted writers after it was found that the company had illegally downloaded their published works for similar training purposes. The terms of that agreement dictated that the 500,000 authors involved in the case would get $3,000 per work. The $1.5 billion looks like a big number, but not so much when broken down like that. Also, Anthropic is worth around $350 billion.

In the Bartz case, Judge William Alsup ruled that it was legal for Anthropic to train its models on copyrighted content but not legal to acquire that content via piracy. We'll have to wait and see how this new suit shakes out. The legal precedent here seems to suggest that if Anthropic would have just spent a buck on each copyrighted song, then they'd be in the clear. That's an odd distinction when it comes to building an entire company around snatching up copyrighted content, but whatever.

This article originally appeared on Engadget at https://www.engadget.com/ai/music-publishers-sue-anthropic-for-3-billion-over-flagrant-piracy-185459358.html?src=rss

©

© Anthropic

A logo.
  •  
❌